
Your local setup, datacenter-grade.
You've maxed out the wall socket. Keep root access and get far bigger silicon.
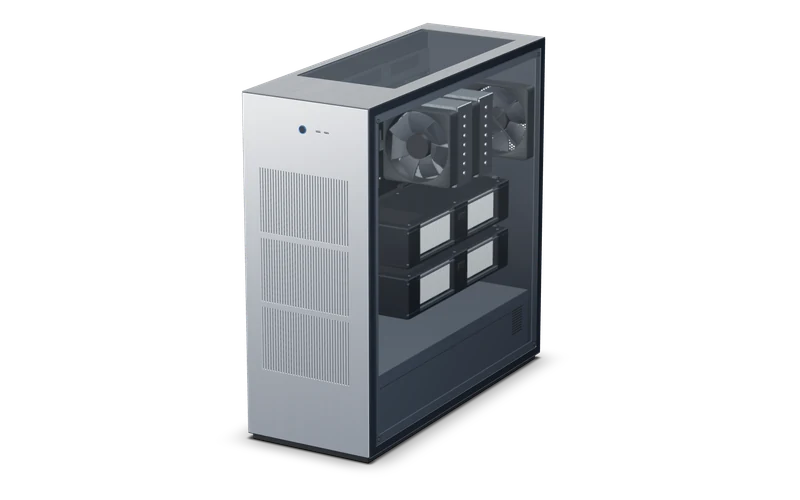
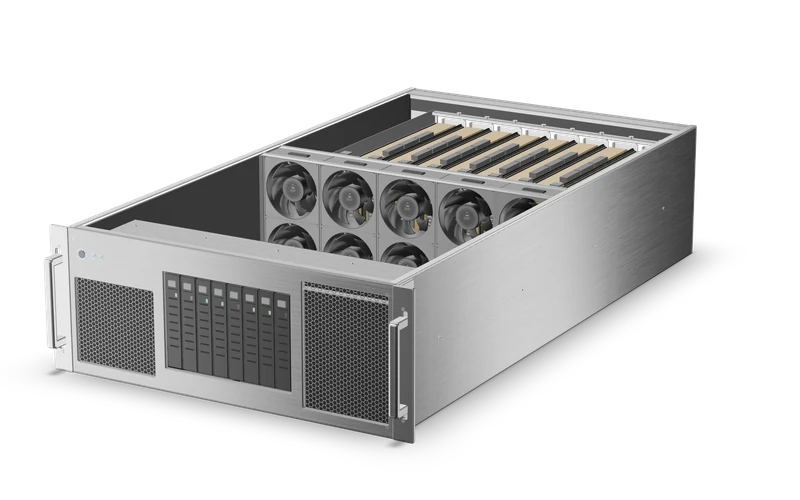
Most VRAM per machine, on one scale
Blue bays are the starting build. Grey bays are room to add.
- RTX 509032 GB GDDR7 · 1.8 TB/s per card32 GBFrom $7,880
- Workstation RTX 509032 GB GDDR7 · 1.8 TB/s per cardUp to 64 GBFrom $12,506
- RTX PRO 6000 Server Edition96 GB GDDR7 · 1.6 TB/s per cardUp to 768 GBFrom $99,971
- H200 NVL141 GB HBM3e · 4.8 TB/s per card1,128 GBFrom $329,032
Configurable builds: parts at our landed cost plus one visible 5% Build & AI-Guarantee fee. Every part is on the build sheet.
Keep the workload. Change its home.
Your model, weights and application
Conceptual hardware views. The catalog gives actual memory and expansion bands. Total VRAM across GPUs is not a single allocation: runtime, interconnect, precision and context determine fit. We can also ship the build to you.
How it runs
We take the pager.
Power, cooling, bandwidth and monitoring become our problem. The machine stays yours, bare metal, and insured while it sits in our rack.
- redundant power
- N+1
- monitoring and on-call
- 24/7
- GPUs tested under full load
- 100%
Rather run it yourself? We build it by hand and ship it to you.
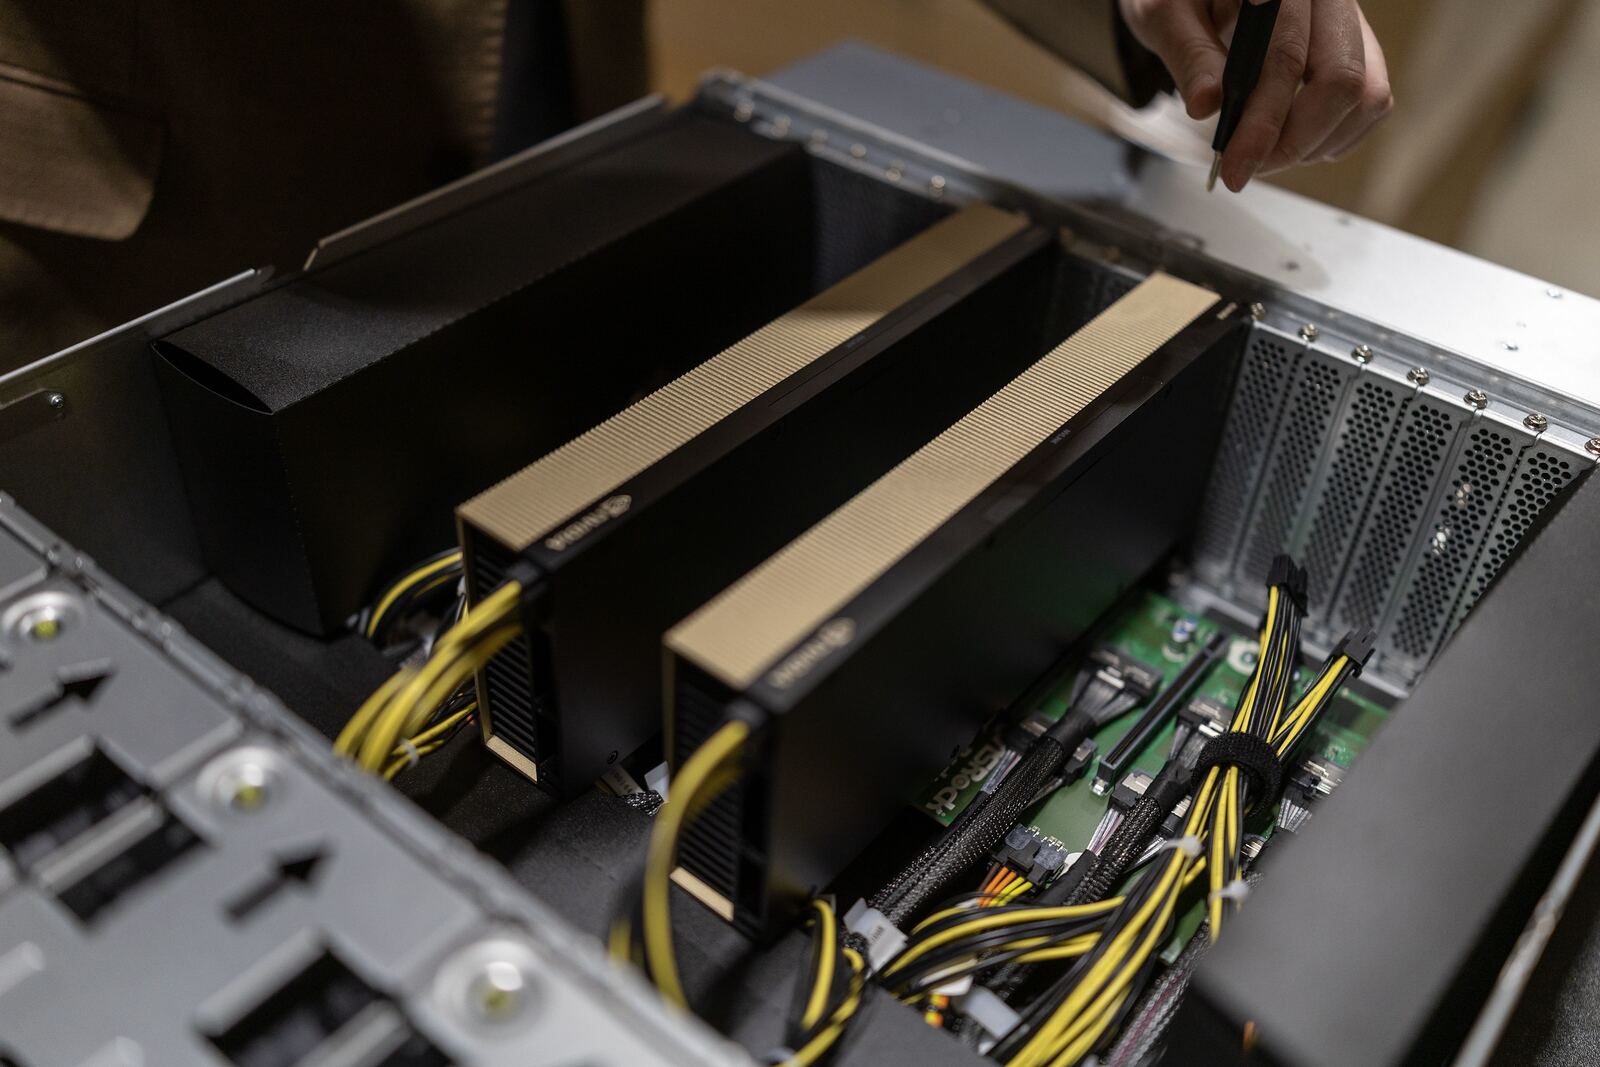
Homelab questions.
Talk specs with us.
Bring your model list and target tokens per second, and we'll spec the box together.
Or message us: iMessage +1 (332) 324-8327Telegram @b3iqbot