
Own your inference. Make the bill predictable.
A metered API prices every token. A machine you own prices the month.
import os
from openai import OpenAI
client = OpenAI(
base_url="https://b3iq.org/v1/api",
api_key=os.environ["B3IQ_API_KEY"],
)
reply = client.chat.completions.create(
model="qwen3.8:27b-bf16",
messages=[
{"role": "user", "content": "Hi"}
],
)
Replace the example model with an ID from client.models.list(). It must be served by your machines and available to this key.
QuickstartYour key, your hardware.


- Your applicationYour app | OpenAI SDK
- B3IQ gatewayKey and machine scope checked
- Your machineRun on your machine



Same code at any size.
Add machines. The endpoint doesn't change.
Your account, your machines.
Keys route only to machines owned by their account or organization. Narrow a key to the machines that should serve that app.
Sized to your model.
On the call, we size the build to the models you run: VRAM, throughput and card count.
What do you run today?
What you pay for
Every token
With B3IQ: The machine, plus Managed Hosting monthly
Where it runs
Their servers
With B3IQ: Your machine in Oregon
Who else is on it
Every other customer
With B3IQ: Nobody
Who fixes it at 3 a.m.
Their on-call team
With B3IQ: Our engineers on site, for the hardware
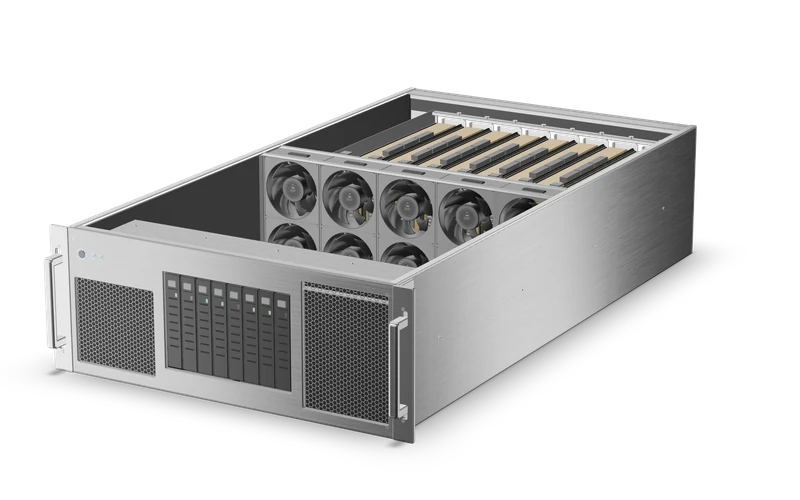
The whole machine.
8 cards and 1,128 GB of GPU memory in one chassis.
H200 NVL
- VRAM
- 141 GB HBM3e
- per card
- Bandwidth
- 4.8 TB/s
- per card
- Lead time
- 6–8 weeks
Starting at $329,032
Before you switch.
Bring your token bill.
We size a machine against your real usage and tell you whether owning beats the API yet.
Or message us: iMessage +1 (332) 324-8327Telegram @b3iqbot