Compare every machine. Speed follows bandwidth.
Each token reads the model's weights from GPU memory, so tokens per second is roughly the memory bandwidth divided by the model's size in memory.
Fastest memory first.
Machines B3IQ sells, ranked by memory bandwidth per GPU
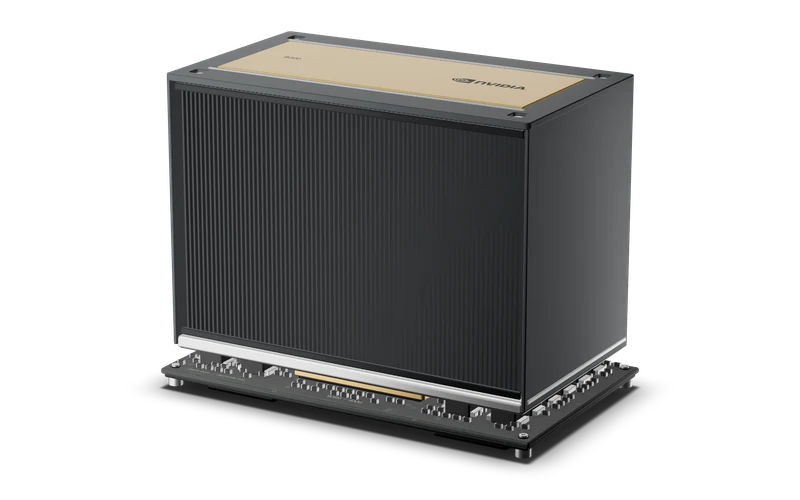
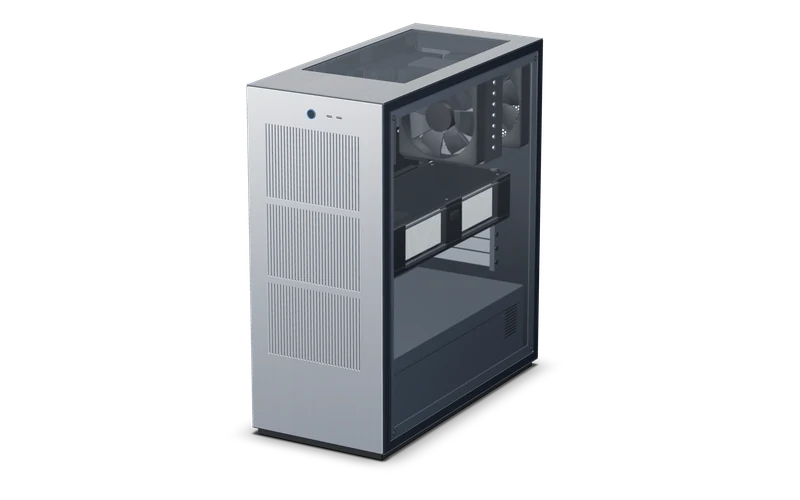
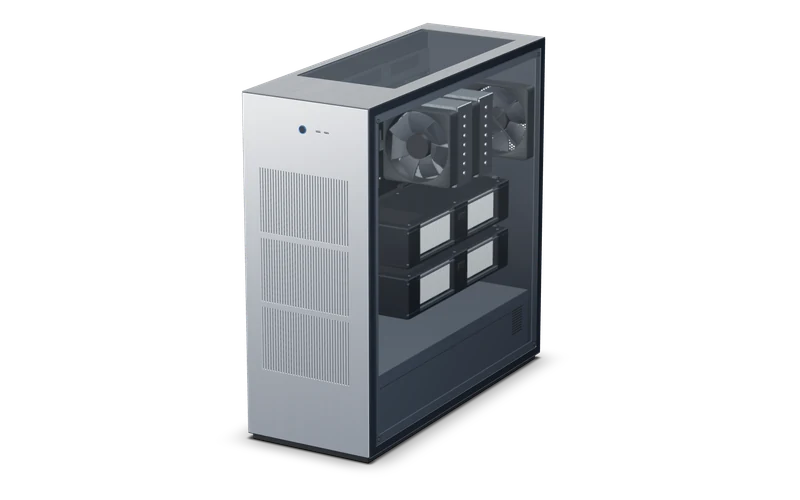
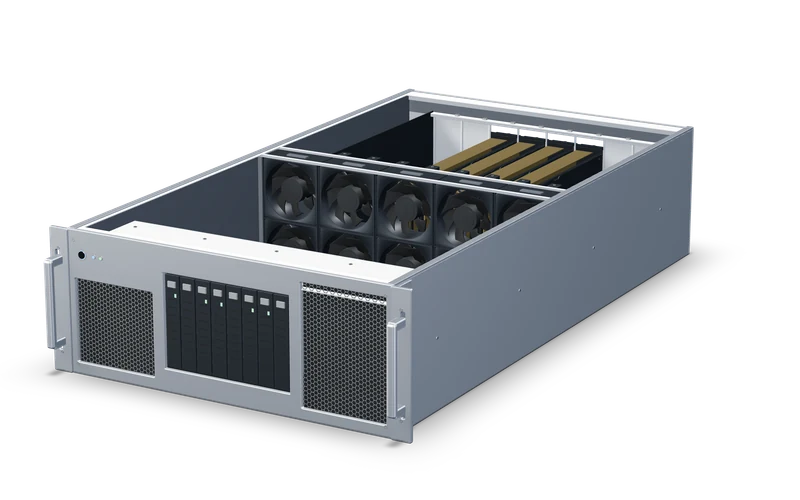
Prices are our landed component cost plus one 5% Build & AI-Guarantee fee, with no markup on parts. Configure the exact build on the next step.
Read the build behind the numbers.
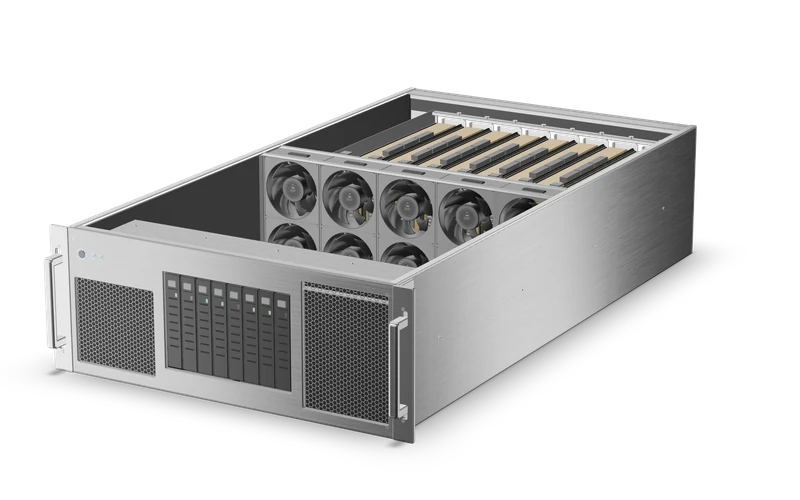
H200 NVL
- Memory per GPU
- 141 GB HBM3e
- Bandwidth per GPU
- 4.8 TB/s
- Installed GPU memory
- 8× · 1.13 TB
- GPU interconnect
- NVLink supported
Installed GPU memory is spread across cards. Interconnect support does not establish model fit or a single shared memory pool; placement, runtime and workload still matter.
Inspect this machine ↗Exterior references; views are framed individually, not at one physical scale. Model fit depends on the runtime, cache and workload. Catalog specifications describe the offered build. The dated community workload references below describe separate runs, not measured performance of this machine.
Spec sheet.
Memory
H200 NVL$329,032 | RTX PRO 6000 Server Edition$99,971 | RTX 5090$7,880 | Workstation RTX 5090$12,506 | B300$560,000 | |
|---|---|---|---|---|---|
| GPU memory | |||||
| System memory | DDR5 RDIMM · 1536 GB | DDR5 RDIMM · 512–768 GB | DDR5 UDIMM (consumer) · 64–128 GB | DDR5 RDIMM · 64–512 GB | On request |
Build
| Form | 4U rack | 4U rack | Prosumer tower | Workstation tower | HGX rack |
|---|---|---|---|---|---|
| NVLink | Yes | No | No | No | Yes |
| CPU | 2× AMD EPYC 9355 (32c) | 2× AMD EPYC 9355 (32c) | Ryzen 9 9950X (16c) | Threadripper PRO 9955WX (16c) | On request |
| Storage | 4 TB NVMe | 4 TB NVMe | 2 TB NVMe | 4 TB NVMe | 960GB NVMe boot drive + E1.S NVMe data storage, configurable to your workload |
| Power at full load | 6 kW | 2.8 kW | 1.6 kW | 2.4 kW | On request |
| Lead time | 6–8 weeks | 6–8 weeks | ~1 week | ~1 week | Preorder |
Measured speed.
Tokens per second and time to first token on open models, one row per hardware. Each row's fastest run is a different model, so compare within a row, not across rows.
These are attributed community runs, not measurements of a B3IQ build. No B3IQ workload benchmark is published here; validate your model, precision, context and concurrency on the configuration you plan to use.
Measured throughput by hardware
Community rows come from the LocalMaxxing community. Snapshot from May 2026. localmaxxing.com
Torn between two?
Next: which models fit